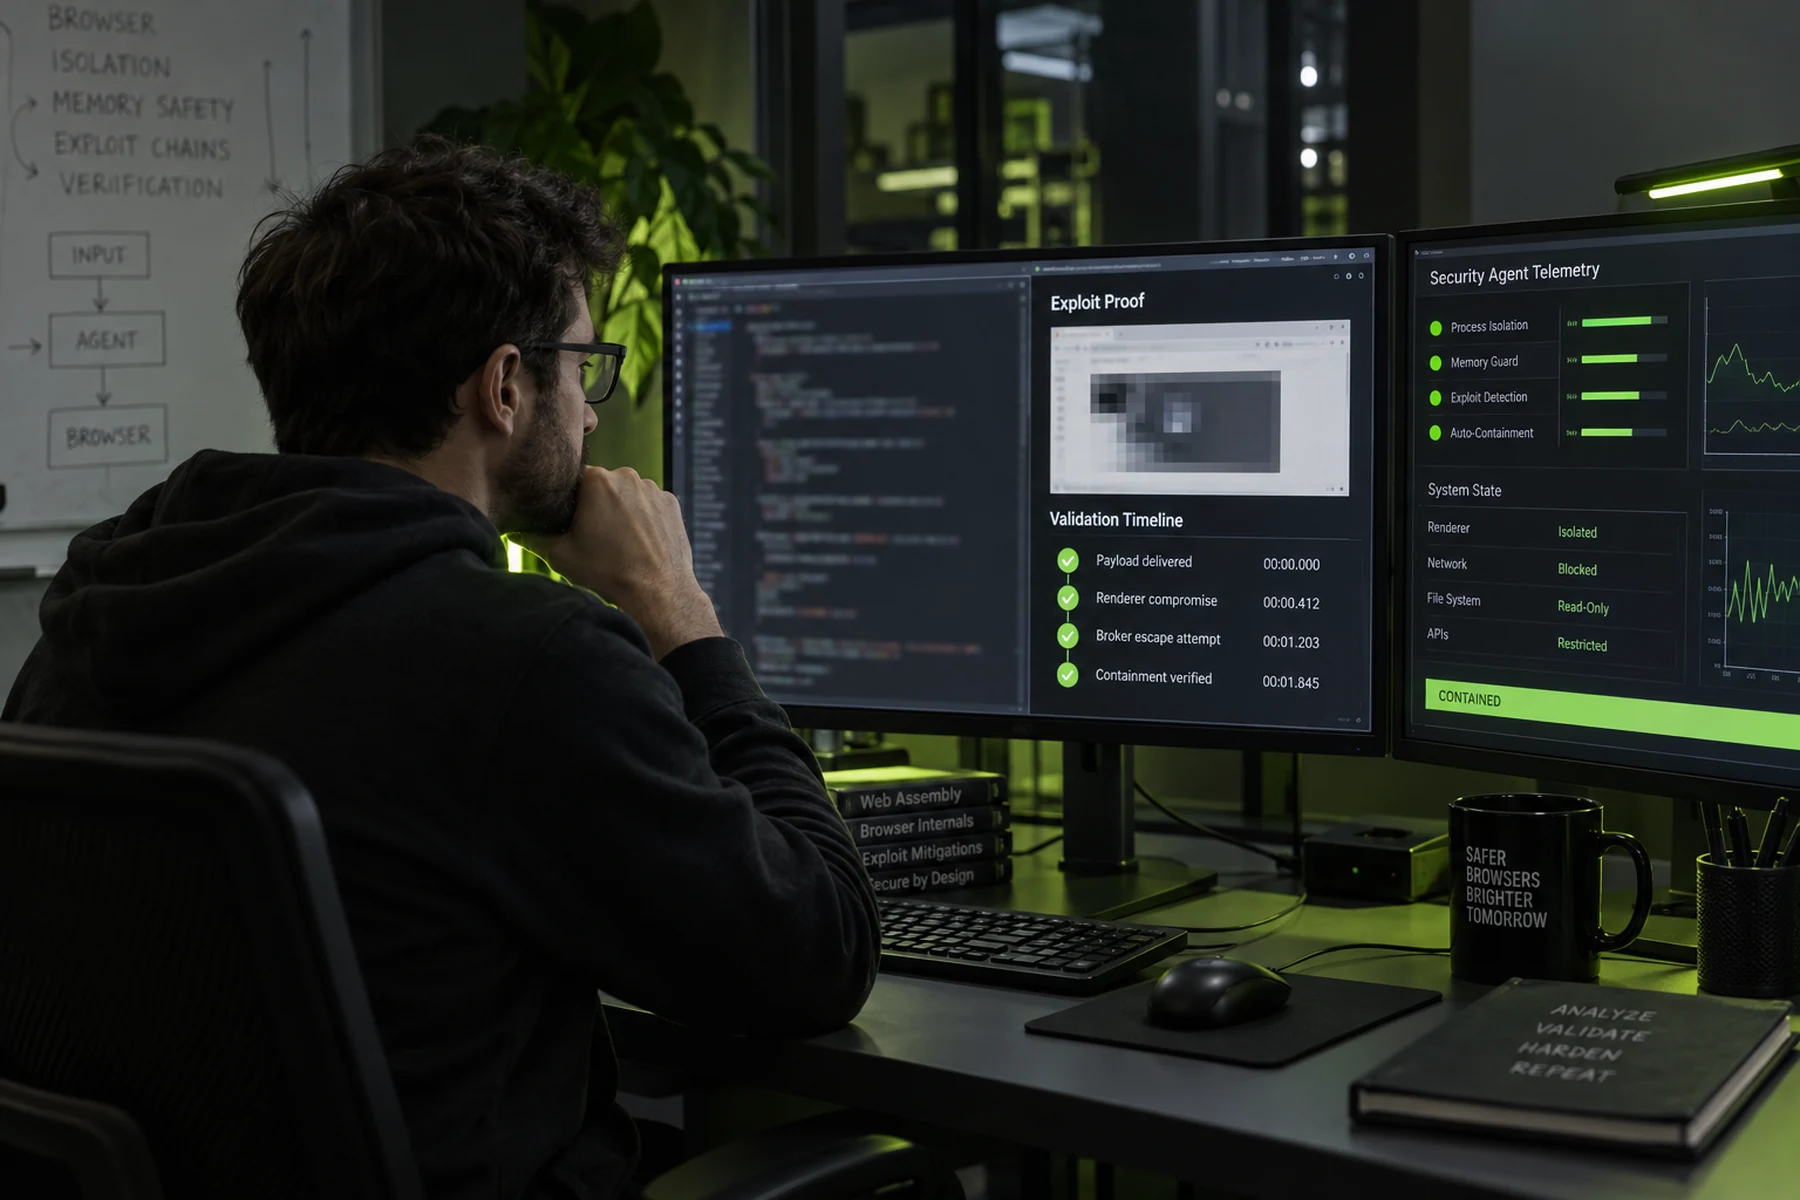
Google has described PageBreak, an internal security agent built to find and validate cross-site scripting flaws in first-party web applications. The timing matters: security teams are receiving more model-generated reports, but many are unverified hypotheses. A system that produces a reproducible proof can reduce triage cost—if its test environment, permissions, and false-negative boundaries are visible.
Quick scan
In brief
Google says PageBreak found two XSS vulnerabilities across hundreds of applications while rejecting large volumes of noise.
The agent runs browser-based validation rather than stopping at a static suspicion.
A low alert count can indicate precision, missed coverage, or both; external replication and disclosure outcomes matter.
Why proof quality matters more than alert volume
Google says PageBreak found two XSS vulnerabilities across hundreds of applications while rejecting large volumes of noise. The relevance to “Why proof quality matters more than alert volume” is direct: generated proof can still target the wrong state or depend on test-only behavior. Measure verified findings per reviewer-hour under the same permissions, version, and workload described by the source, then repeat the test with an ordinary operator who did not prepare the demonstration.
Keep the claim narrow enough to disprove. For verified findings per reviewer-hour, publish the denominator, failed cases, human corrections, and time window. The limitation—generated proof can still target the wrong state or depend on test-only behavior—should appear beside the result so a reader can distinguish demonstrated capability from dependable operation.
The sandbox and permission boundary
Start with the documented point: The agent runs browser-based validation rather than stopping at a static suspicion. For the sandbox and permission boundary, map the people, data, permissions, and recovery steps touched by that claim. The known boundary is broad browser automation creates credentials and data-handling risk; design the pilot so this condition is visible instead of filtered from the dashboard.
Use time from report to safe patch as a decision measure, not a vanity number. Record the pre-deployment baseline, the software build, exceptions, and any work moved to another queue. A local improvement counts only when the same evidence can be reproduced after the launch team leaves.
Evidence map
What to separate
| Layer | Focus | What the evidence says |
|---|---|---|
| Signal | Why proof quality matters more than alert volume | Google says PageBreak found two XSS vulnerabilities across hundreds of applications while rejecting large volumes of noise. |
| Constraint | The sandbox and permission boundary | Start with the documented point: The agent runs browser-based validation rather than stopping at a static suspicion. |
| Proof point | What a security team should measure during a pilot | The headline does not settle what a security team should measure during a pilot. |
What a security team should measure during a pilot
The headline does not settle what a security team should measure during a pilot. The verified evidence is that a low alert count can indicate precision, missed coverage, or both; external replication and disclosure outcomes matter. The unresolved constraint is that a vendor’s internal estate is not a representative benchmark. Put those statements together before forecasting adoption, savings, safety, or user impact.
A practical check is incidents caused by test automation. Test it during partial outages, stale data, revoked access, and a handoff to a human owner. If the workflow cannot explain what happened and preserve the evidence needed for rollback, the product is still a supervised experiment.
How responsible disclosure changes the workflow
Treat “How responsible disclosure changes the workflow” as an operational question. Google says PageBreak found two XSS vulnerabilities across hundreds of applications while rejecting large volumes of noise. Now identify what must remain true for that result to transfer outside the vendor’s environment. In particular, precision without measured recall can hide missed vulnerabilities. That condition belongs in the acceptance criteria rather than a footnote.
Track false-positive rate after reproduction by user group and failure type. Keep raw examples, including false alarms and missed cases, because an average can hide the exact scenario that creates harm. The owner should be able to pause the rollout without losing data or the previous workflow.
A field test for verified findings per reviewer-hour
A buyer or policy team should read a field test for verified findings per reviewer-hour through two records. The first is the source claim: The agent runs browser-based validation rather than stopping at a static suspicion. The second is the counter-record: generated proof can still target the wrong state or depend on test-only behavior. Neither should be replaced by a screenshot of the best run.
For coverage across authenticated workflows, specify who collects the number, who audits it, and which cases are excluded. Re-run the measure after an integration change and after a real incident. A result that survives those moments has more weight than a benchmark optimized for launch day.
Where false-positive rate after reproduction can mislead
The user-facing consequence of where false-positive rate after reproduction can mislead may be a new prompt, delay, approval, or unexplained refusal. A low alert count can indicate precision, missed coverage, or both; external replication and disclosure outcomes matter. Follow that path from interface to backend control, while keeping broad browser automation creates credentials and data-handling risk visible as the principal failure condition.
Measure verified findings per reviewer-hour alongside accessibility, offline behavior, support load, and recovery time. If the system saves minutes for the main path but strands edge cases without an owner, the operational cost has merely moved out of view.
The operator view of time from report to safe patch
For the operator view of time from report to safe patch, separate architecture from governance. Google says PageBreak found two XSS vulnerabilities across hundreds of applications while rejecting large volumes of noise. Architecture may enable the behavior; it does not decide who may use it, how long data persists, or when a human must intervene. The constraint is that a vendor’s internal estate is not a representative benchmark.
Turn time from report to safe patch into a control with a threshold and an escalation route. Preserve the model or software version and input conditions for every exception. That record lets an independent reviewer reproduce the conclusion instead of trusting the label attached to the feature.
A failure drill for generated proof can still target the wrong state or depend on test-only behavior
The next credible update on a failure drill for generated proof can still target the wrong state or depend on test-only behavior needs a falsifiable result. Today’s anchor is: The agent runs browser-based validation rather than stopping at a static suspicion. The strongest reason for caution is that precision without measured recall can hide missed vulnerabilities. Define in advance which observation would strengthen the claim and which would reverse it.
Monitor incidents caused by test automation over a stated period, but pair it with incident narratives and rollback data. Numbers show frequency; cases show mechanism. Together they reveal whether the change is robust, merely fast, or dependent on hidden human supervision.
What independent evidence should show
A low alert count can indicate precision, missed coverage, or both; external replication and disclosure outcomes matter. The relevance to “What independent evidence should show” is direct: generated proof can still target the wrong state or depend on test-only behavior. Measure false-positive rate after reproduction under the same permissions, version, and workload described by the source, then repeat the test with an ordinary operator who did not prepare the demonstration.
Keep the claim narrow enough to disprove. For false-positive rate after reproduction, publish the denominator, failed cases, human corrections, and time window. The limitation—generated proof can still target the wrong state or depend on test-only behavior—should appear beside the result so a reader can distinguish demonstrated capability from dependable operation.
The update trigger after launch
Start with the documented point: Google says PageBreak found two XSS vulnerabilities across hundreds of applications while rejecting large volumes of noise. For the update trigger after launch, map the people, data, permissions, and recovery steps touched by that claim. The known boundary is broad browser automation creates credentials and data-handling risk; design the pilot so this condition is visible instead of filtered from the dashboard.
Use coverage across authenticated workflows as a decision measure, not a vanity number. Record the pre-deployment baseline, the software build, exceptions, and any work moved to another queue. A local improvement counts only when the same evidence can be reproduced after the launch team leaves.
A bounded deployment decision
The headline does not settle a bounded deployment decision. The verified evidence is that the agent runs browser-based validation rather than stopping at a static suspicion. The unresolved constraint is that a vendor’s internal estate is not a representative benchmark. Put those statements together before forecasting adoption, savings, safety, or user impact.
A practical check is verified findings per reviewer-hour. Test it during partial outages, stale data, revoked access, and a handoff to a human owner. If the workflow cannot explain what happened and preserve the evidence needed for rollback, the product is still a supervised experiment.
Questions the next report must answer
Treat “Questions the next report must answer” as an operational question. A low alert count can indicate precision, missed coverage, or both; external replication and disclosure outcomes matter. Now identify what must remain true for that result to transfer outside the vendor’s environment. In particular, precision without measured recall can hide missed vulnerabilities. That condition belongs in the acceptance criteria rather than a footnote.
Track time from report to safe patch by user group and failure type. Keep raw examples, including false alarms and missed cases, because an average can hide the exact scenario that creates harm. The owner should be able to pause the rollout without losing data or the previous workflow.